Extra line breaks are created when the line break converter is turned on for an input format (such as Filtered HTML) and the content contains tags that are upper case. For example: <P>foo</P> turns into something like: <p></p><P>foo</p>
Uppercase <TABLE><TR><TD>...</TD></TR></TABLE> tags are even worse.
The function _filter_autop needs to be more case insensitive. There are a lot of preg_replace() calls, but only a couple of them are case insensitive. I would think that any that are looking for a tag name of any kind should be case-insensitive. For example, this line:
$chunk = preg_replace('!<p>\s*(</?'. $block .'[^>]*>)!', "$1", $chunk);
should be (added the i):
$chunk = preg_replace('!<p>\s*(</?'. $block .'[^>]*>)!i', "$1", $chunk);


Comments
Comment #3
vm commentedI believe this is by design:
see: http://www.w3schools.com/Html/html_elements.asp
Comment #4
ampersat commentedI understand why this might be by design (and I personally prefer lowercase tags whenever possible), but there's a problem with that. Drupal's basic philosophy for user data allows almost anything to be entered into the web interface and subsequently stored in the database (including upper case tags). Formatting, filters, etc. are applied at display time.
This means that output filters need to be able to handle user data...even data that is not standards-compliant.
Otherwise, there needs to be a way to force standards compliance at input, which I'm not sure there is currently.
Comment #5
damien tournoud commented@bounsy: ensuring HTML compliance is the job of the HTML corrector, that you should run as early as possible in your filter chain. I'm not sure that the Drupal 6 version of the HTML corrector does that well, but the Drupal 7 proposed version (#374441: Refactor Drupal HTML corrector (PHP5)) surely does.
Comment #6
ampersat commentedThat's useful to know. It does make me wonder, though: Why does the default configuration have the following weights?
URL filter: 0
HTML filter: 1
Line break converter: 2
HTML corrector: 10
If HTML correction is so important to run early, why is it so heavily weighted to run at the end by default? Shouldn't the default have the HTML corrector before the Line break converter at least?
By the way, I just moved Line break converter to the end and everything works great now. Hopefully the Line break converter doesn't produce anything that needs to be corrected, since it is no longer being corrected by the HTML corrector.
Comment #7
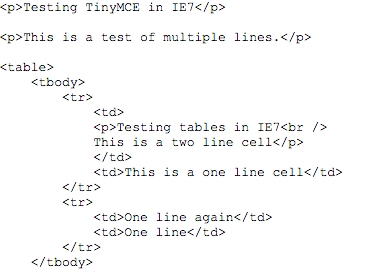
imrook commentedI found this post after running into the same issue myself. Thanks Damien and bounsy for the suggestion to use the HTML corrector filter and lower the weight. This fixed simple cases for me, but I found there is a bug in the HTML corrector filter: Opening tags are not lowercased. It's actually apparent in the example in the opening post. Here's HTML straight from the node_revisions table that was generated in TinyMCE on IE7:
The HTML that gets rendered is the following:
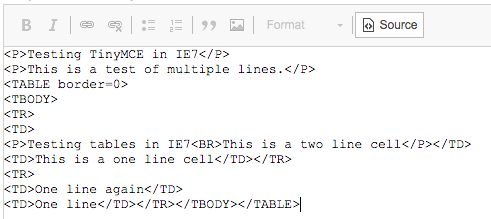
Upon inspecting the code for the HTML corrector filter, I found that it only performs strtolower() on the closing tag. The attached patch also calls strtolower() on the opening tag. With the patch applied, I get the following HTML output:
Comments on this patch are welcome.
Comment #8
c960657 commentedThis may be a configuration issue, but in that case I think the default filter configuration is problematic.
To reproduce this:
1. Install HEAD
2. On admin/config/content/formats/2, add these to the list of allowed tags:
<p> <br> <table> <th> <td> <tbody>3. On node/add/article, insert the HTML code from the first code block in comment #7. Then save the node.
The output will look something like the second code block in #7.
You could argue, that the HTML corrector should be run first. I'm not sure about the consequences of this. A less invasive solution is to make the Line break converter filter case insensitive when looking for tags, like e.g. the URL filter is.
This patch basically adds an
imodifier to all the regex patterns in _filter_autop(). As a clean-up, it also changes the patterns to use the same delimiter character,`instead of a number of different characters, and changes a few strings to use single quotes.The patch has been hand-edited in order to make it easier to review.
Comment #9
damien tournoud commentedAgreed on #8. Could we slightly extend the existing autop tests?
Comment #10
c960657 commentedAdded a few tests. Also made the patterns accept
<br>and<br/>(both case-insensitive) in addition to<br />.Comment #11
c960657 commentedReroll.
Comment #12
c960657 commentedReroll that applies to both 7.x and 8.x.
Comment #13
c960657 commentedComment #14
kscheirer#13: filter-autop-5.patch queued for re-testing.
Comment #16
c960657 commentedComment #27
pameeela commentedThis seems to be working fine now, have copied the markup from #7 with a bunch of different settings checked for the text format but it always works.
Before:
After: